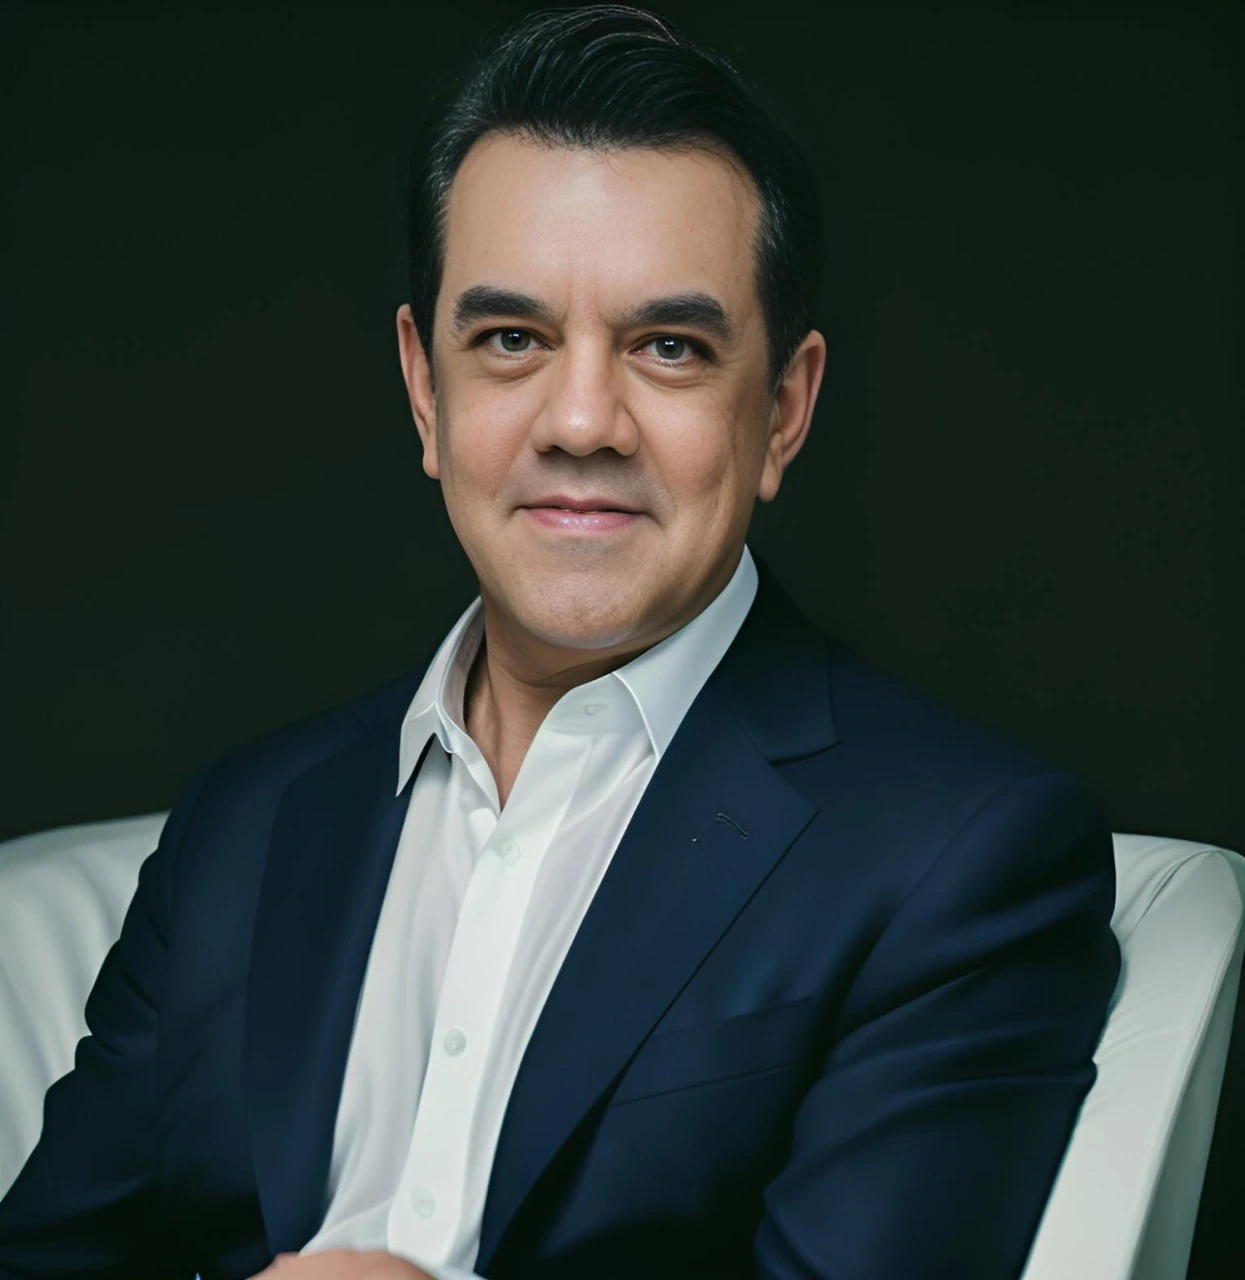
The interview
01
01 · THE DECISION BEFORE THE AI
JLP Décryptage
You have argued that industrial enterprises are overwhelmed by siloed data, slow decisions and reactive planning. Yet at Gulfood 2026, you offered a more focused prescription: “Don’t attempt to scale AI; attempt to scale your decision first and pick that high-stakes decision.” If systemic fragmentation is the problem but a single decision is the entry point, what mechanism prevents a successful AI deployment from becoming another isolated optimization layer? More specifically, how does SWARM’s Challenge Engineering approach allow knowledge learned around one decision to improve the wider operating system rather than creating a new silo?
Shail Khiyara
Before a concert starts, the room is forty instruments of pure noise. Nobody fixes that by tuning every instrument at once. One oboe plays a single note, the A, and the rest of the orchestra finds it. That note isn't chosen because it's the loudest or the most out of tune. It's chosen because it's the one the whole room needs to organize around.
The fragmentation isn't in the business objectives. Most operators know exactly what they're solving for, protect margin, hit service levels, manage working capital. The fragmentation is in the data that would need to come together to actually make the decision behind that objective. Those are two different diagnoses, and starting in the wrong one is how companies end up scaling AI instead of scaling a decision.
Our sequence starts with the objective, not the data. We get specific about the economics first, what this decision is worth, what it costs when it's made badly, what the unit economics underneath it actually look like. Only once that's understood do we go looking for the data that feeds it, wherever it happens to live. Start from the data and you inherit whatever silo structure already exists. Start from the decision's economics and the data requirement gets defined by the problem, not by the org chart.
That's also what stops it from becoming a new silo. It isn't a shared database or a common schema. It's that every engagement re-derives the economics of the decision in front of us before touching the data at all, and that discipline is what carries forward. Two decisions in different parts of the business will pull from entirely different systems.
This is a systems thinking approach to the problem before it's a piece of architecture. The second decision doesn't need a single byte of what the first one used. It only needs the same discipline that found the first note.
02
02 · WHERE DOES AGENTIC ACTION ACTUALLY BEGIN?
JLP Décryptage
In the book you co-authored on agentic AI, the distinction between reactive systems and systems that can perceive, reason and act is fundamental. In an industrial environment, however, the transition from recommendation to action is precisely where capital, liability and human judgment enter the picture. When SWARM identifies an optimal inventory, production or logistics decision, what happens next in a real deployment? Does the system write the decision back into an ERP or operational system and execute it, or does a human approve it first? What percentage of the decisions SWARM currently influences are actually executed without human approval, and what determines when that threshold can increase?
Shail Khiyara
A self-driving car will hand control back to you the moment it senses something it can't fully resolve, a merge, a construction zone, rain on the sensor. Nobody calls that a failure of autonomy. It's the design working correctly. Trust gets built one uneventful mile at a time, not granted on day 1.
That's close to where SWARM is today, and I'd rather say that plainly than dress it up. Right now, in every live deployment, SWARM produces a recommendation. A human implements it. Human approval is universal, not for one decision type or one customer. When I say we're agentic in the sense my book describes, perceiving, reasoning, and acting, I mean that's the direction of travel.
That sequencing is deliberate, and it's also what most customers actually want. Almost nobody asks us to hand over the wheel on day 1. They want to watch the model reason through real decisions, validate that its logic holds against what their own operators would have done, and only then talk about what deeper integration looks like. Validate, deploy, then integrate into their systems directly. That's not caution we impose on them. It's the sequence customers choose, because trusting a recommendation you can check is very different from trusting an action you can't take back.
What determines when a decision class is ready to move from human-implemented to system-executed is the same three things we watch in any HITL system: how often the human overrides what we recommend, how expensive a wrong call is to unwind if it does go live, and how quickly the outcome becomes visible. A pricing call with same-day feedback earns autonomy faster than a production schedule that commits a week of capital. We're not moving toward one autonomy switch for SWARM. We're moving toward dozens of them, each turned up only as fast as a specific decision earns it.
03
03 · THE EVIDENCE
JLP Décryptage
What metrics do you require internally before you're willing to say SWARM — rather than the surrounding transformation programme — caused an operational improvement? Can you walk through that with a real example?
Shail Khiyara
Correlation is cheap. Any vendor can point at a metric that moved while their software was in the building. Causation costs more, and the price is a standard you're willing to apply even when it produces an answer you don't like.
Mine has three parts. First, the process has to be narrow enough that I can name everything else that could plausibly explain the result, and rule each one out. A company-wide metric that moves for a dozen reasons tells me nothing. A single, specific process does. Second, I need a baseline measured before deployment, on that exact process, not a general sense of "it used to be slower." Third, the customer has to be willing to put their name on the causal claim, not just the outcome. A result nobody will attach their name to is a rumor, not evidence.
Industrial Labs is where all three lined up. The before state was one identifiable process, manual, spreadsheet-driven scheduling. We replaced that process with SWARM ENGINE. Nothing else in their operation changed at the same time, no ERP migration, no reorg, no new process discipline layered in alongside us. Turnaround got 32% faster. Analyst workloads got 97% more balanced. When I'm asked whether that's SWARM or something else, I have an answer, because there was almost nothing else it could be.
Not every engagement gives me that clean a test, and I'd rather say so than round up. Some of our work is coordination at a scale where isolating one variable is genuinely harder, Ardent Mills runs SWARM across a large North American milling network to plan product flow across many facilities and customer locations at once. A grower in South America uses SWARM to plan labor and transportation for up to 15,000 field workers, turning a monthly planning cycle into something fast and repeatable. Those are real, deployed, valuable results. I hold them to the same bar, and where I can't fully isolate the number the way I can with Industrial Labs, I say that plainly rather than borrow the confidence of a cleaner case to cover a messier one.
That's the discipline. Not every result gets a number attached to it in public. But every number I do put in public has passed the same test Industrial Labs passed, and I'd rather have fewer numbers I'll defend than more numbers I'd have to walk back.
04
04 · WHEN AGENTS FAIL
JLP Décryptage
Agentic systems introduce failure modes that conventional analytics do not: an error can propagate through a sequence of actions, one agent can consume another agent’s faulty output, and a plausible recommendation can become an operational instruction. In the deployments you have seen at SWARM, which class of failure has proved hardest to control in practice? I am less interested in the theoretical safeguards than in what production experience has forced you to change — in the architecture, the permissions given to agents, or the role of human review.
Shail Khiyara
An engineer who optimizes one beam in isolation can produce a beautiful calculation and a building that doesn't stand up, because the beam was never the whole system. That's the failure mode that's given us the most trouble, not a bad action, but a technically correct answer to the wrong problem.
We had a case where the model produced what looked like an optimal allocation. Clean numbers, real efficiency gains, nothing wrong with the math. It also violated a labor agreement nobody had encoded as a constraint, because it wasn't in any dataset, it lived in a contract and in the institutional memory of people who'd negotiated it years earlier. An operator caught it before it went anywhere. But that's the pattern that worries me most, not an agent taking a bad action, since nothing executes without a human today, but a recommendation that's locally optimal and globally wrong, confident on the surface, blind to a constraint that was never part of its world in the first place.
The second version of that same failure is upstream, not downstream. Stale or bad data feeding a model doesn't announce itself. It produces a recommendation that looks exactly as clean as a correct one. Garbage in doesn't look like garbage. It looks like confidence.
What that forced us to change wasn't the model. It was where we spend our engineering effort before the model ever runs. We treat constraint discovery as its own explicit step now, sitting down with the people who hold the unwritten rules, labor agreements, compliance limits, relationships, not just the people who own the data, before we let a system optimize anything. Systems thinking isn't a phase you add after the math works. The most dangerous recommendation isn't the one that's wrong. It's the one that's correct and still shouldn't happen.
05
05 · THE ECONOMIC THRESHOLD
JLP Décryptage
You have lived through several generations of enterprise automation, from RPA and intelligent automation to today’s agentic systems. Each generation promised compelling returns, yet each also introduced integration, maintenance and governance costs that were often underestimated. What is your economic test today for deciding that an agentic system is genuinely preferable to a strong operations team using conventional planning software? Is there a threshold in decision frequency, cycle-time reduction, error reduction or payback period below which you would advise a company not to deploy SWARM at all?
Shail Khiyara
I've watched three generations of this promise now, RPA, intelligent automation, and now agentic systems, and the pattern of overpromising is consistent. The vendor sells the decision improvement, the customer discovers the integration and maintenance tail six months in, and the payback period quietly doubles.
But the economic test I actually use isn't about frequency or cost in isolation. It's about simultaneity, and this is the part of the equation most people in this industry still get wrong. A strong ops team can handle a lot of decisions well, as long as those decisions happen one at a time. What breaks a human team, and what conventional planning software was never built for, is a set of decisions that are all moving at once and all touching each other. A change in one facility's capacity shifts the right answer for a facility three states away, in the same hour, while a supplier delay is simultaneously changing the constraint on a third decision entirely. No person, no matter how good, is holding all of that in their head at the same time. That's not a volume problem. It's a simultaneity problem, and it's poorly understood precisely because most automation, RPA included (rules based), was built to speed up one decision at a time, not to hold many interacting decisions in view together.
That's where the real economics show up, and it's also my actual threshold. A decision made twice a year by three experienced people in a room is not a candidate, no matter how much value is on the table, because there's nothing simultaneous about it for a system to add value to. But a set of decisions that are genuinely interdependent, where the right answer in one place depends on what's happening in three other places at the same moment, is exactly where a strong ops team runs out of runway no matter how talented they are, and it's where the network effect actually starts compounding instead of just adding up.
If I can't point to that kind of simultaneity, multiple decisions, multiple sites, all moving and touching each other in real time, I tell the prospect not to buy. We've walked away from deals on that basis. A single, isolated decision doesn't need an agentic system. It needs a good spreadsheet and someone who knows the business.
06
06 · WHO STILL HAS THE RIGHT TO SAY NO?
JLP Décryptage
You have argued that AI should augment people rather than replace human judgment. At the same time, the value proposition of agentic AI depends partly on allowing systems to act with increasing autonomy. Where does SWARM draw the non-negotiable boundary today? Which operational decisions should an agent never be permitted to execute without human approval, regardless of its historical accuracy? And once an enterprise deliberately authorizes an agent to cross that boundary, how should responsibility be allocated when the resulting decision is wrong?
Shail Khiyara
Accuracy is not the boundary. A system can be right 98% of the time and still not deserve the keys, if the 2% it gets wrong is the kind of wrong a business can't undo. And a system with a much thinner track record can be trusted sooner, if a mistake costs almost nothing to fix. The question was never how often is it right. It's what happens when it isn't.
That's why the line I won't move is drawn around consequence, not confidence. Capital committed beyond a routine amount. Anything touching a person's safety. Anything with regulatory or compliance exposure, where the rule exists because someone got hurt before the rule did. Those aren't places I want a system optimizing for the number it was trained on, without a person in the room asking whether that number still means what we think it means.
Here is the part I'd say to any executive weighing this, not just to you. I am on record as having often said - Silicon (AI) needs Carbon (humans). A model can hold a thousand variables at once and never get tired. It cannot smell a problem before the data shows it, and it has never had to look a person in the eye and explain a decision that cost them something. That instinct is not a dataset we're waiting to collect. It is a different kind of intelligence, and the decisions I just named are exactly the ones where that kind of intelligence still has to sign its name.
Responsibility follows the same logic. When a company deliberately authorizes an agent to cross that line and gets it wrong, the responsibility does not move to the system. It stays with whoever set the threshold that let it act, a named person, not "the AI" and not "the vendor." We say this to customers before we ever discuss widening autonomy on a decision. If nobody in the room will put their name on that accountability, we don't widen it.
Silicon can carry the weight of the calculation. It cannot carry the weight of the consequence. That stays with us.
07
07 · THE FALSIFIABILITY TEST
JLP Décryptage
Let us make the proposition measurable. Over the next 24 months, what three or four thresholds would you accept as evidence that industrial agentic AI is delivering what you believe it should — and, equally importantly, what results would force you to conclude that the thesis has been overstated? I am thinking in terms of metrics such as the percentage of decisions executed autonomously, human reversal rates, decision error rates, payback periods or measurable economic value created. What numbers would you personally be willing to be judged against?
Shail Khiyara
A couple of things come to mind. Override trust is key - the override rate on decisions where industrial agentic AI has been live at least 6 months should trend down, not flat, over that period. Right now every recommendation goes through a human before it moves. That's correct today. If, 24 months from now, the people approving those recommendations are still overriding them at the same rate they did on day 1, the system isn't earning trust, it's being tolerated, and I'd have to say the technology isn't doing what it claims to do.
Also, today most industrial AI systems execute with a human approving it first. I expect that to change for a defined set of low-consequence, reversible calls, pricing adjustments, routine reallocations, decisions cheap to unwind if we're wrong. I'm willing to bet that number moves meaningfully off zero within 24 months. If it's still zero everywhere, for everyone, two years from now, that's not caution. That's the thesis failing to hold.
The agrifood and manufacturing industries are aging out. A generation of operators who've spent 30 years learning what a bad harvest looks like, or what a labor agreement actually allows before anyone reads the fine print, is retiring, and most of that judgment leaves the building with them. I want to measure how much of that judgment survives their departure inside the constraint libraries we build with them while they're still there. Call it a knowledge retention rate. If a veteran operator retires and the decisions made with an industrial AI system six months later are noticeably worse without them, we captured nothing real, we just built a nicer interface on top of a person. If they retire and the system keeps making the calls they would have made, something durable got transferred before it walked out the door. I know that framing makes some people uneasy, it sounds like I'm describing digitizing a person. I'd rather call it what it is. The alternative isn't that the knowledge stays human. The alternative is that it retires and is simply gone.
08
08 · THE COMPANY AFTER AGENTIC AI
JLP Décryptage
If systems like SWARM eventually become genuine participants in operational decision-making, the consequence will extend beyond productivity. They could change what a plant manager manages, what a supply-chain analyst is employed to do, how authority is distributed between headquarters and the field, and ultimately how organizations define accountability. By 2030, what is the most consequential organizational change you expect to become irreversible if agentic AI fulfils even half of its promise? And what human capability or institutional responsibility would you deliberately preserve from automation, even if keeping it human makes the organization slower or more expensive?
Shail Khiyara
By 2030, the most consequential change won't be what gets automated. It will be what a plant manager or supply chain analyst is actually accountable for once the information-gathering part of their job is gone. Today, most of that role is spent reconciling scattered data before a real decision even gets made. Strip that away, and what's left is smaller in task count and heavier in stakes, the edge cases, the tradeoffs with no clean answer, the moment a constraint that was never in any model, a labor relationship, a safety instinct, a promise made to a community, has to override the optimization. I think that shift is already irreversible. Once an organization sees what its best people can do when they're not buried in reconciliation work, it doesn't willingly go back to burying them in it again.
The part I'd fight to keep human, even at a cost, is the one we talked about earlier. The right to say no, and be right about it, without having to explain that no in language a model can parse. The moment a company requires an operator to justify an override in terms a system understands, the system has quietly become the real decision-maker and the person has become a compliance function wearing a badge. I'd keep that slower and more expensive before I'd let it go, because the alternative isn't a faster version of good judgment. It's the absence of judgment with better packaging.
There's a second thing I'd preserve, and it's the harder one. Somewhere in every plant, there is a person who knows what a problem smells like before the data confirms it, thirty years of pattern recognition nobody wrote down because nobody thought to ask. We can capture some of that in a constraint library if we're deliberate about it while they're still there. We cannot capture the part of it that only exists in a person choosing, in a specific moment, to trust their gut over the number on the screen. That capacity, to override the system and mean it, is not a feature I'm trying to build. It's the thing the whole system exists to serve. Silicon needs carbon. If we ever forget which one is in charge, we haven't built a smarter company. We've just built a faster way to be wrong.
His background
About — Shail Khiyara
Shail Khiyara is the CEO of SWARM Engineering, a decision-intelligence company building AI-powered optimization systems for agrifood and manufacturing. SWARM combines intelligent agents, optimization and domain knowledge to help operations teams make decisions across supply chain, workforce, production and logistics. In June 2026, the company announced a $10 million Series A co-led by S2G Investments and AgRogue Growth Partners.
Khiyara has more than two decades of experience across technology and automation. His background includes Bechtel, senior leadership roles in enterprise software, and a former role as Customer Experience Officer at UiPath. Founder of VOCAL, he also serves as a board member or advisor to technology companies. He contributed to Intelligent Automation – Bridging the Gap between Business and Academia and is among the co-authors of Agentic Artificial Intelligence: Harnessing AI Agents to Reinvent Business, Work and Life. He holds an MBA from Yale, an MS in Civil Engineering, and has completed Executive Education at Harvard Business School.

CEO, SWARM Engineering | Author | Board Member